RAG infrastructure that keeps answers reliable
Accurate answers depend on the pipeline behind the model. We build RAG infrastructure for ingestion, embeddings, retrieval, permissions and evaluation, so quality can be measured and improved.
Book an architecture callSee the ARIA case study Qdrant
 LangChain
 Ollama
 Hugging Face
 PostgreSQL
 n8n
What is RAG infrastructure?
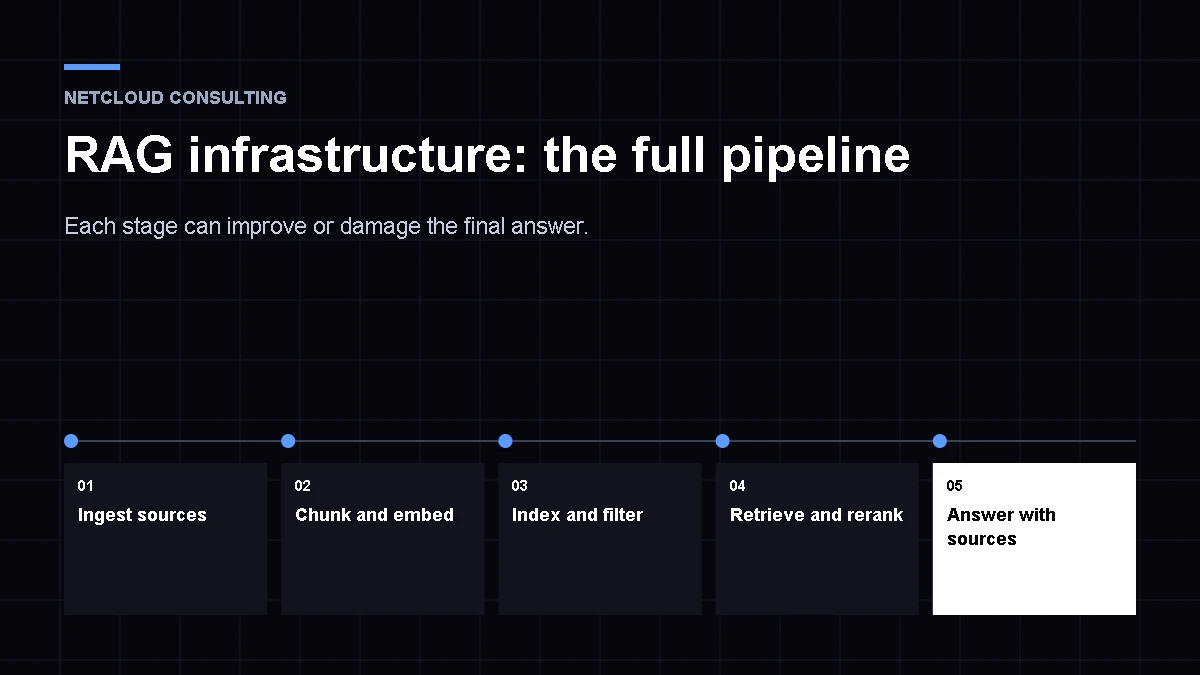
RAG infrastructure is the technical foundation of retrieval-augmented generation. It collects your content, prepares it for search, finds relevant passages for each question and passes them to a language model to answer from.
This page focuses on the underlying platform. For complete assistants and business use cases, see our enterprise RAG systems service, which builds on this foundation.
RAG infrastructure components we deliver
Most RAG quality problems start before the model sees a question.
Ingestion pipelines
Connect documents and business systems, with scheduled and incremental updates.
Chunking and parsing
Handle tables, PDFs and headings without losing meaning.
Embeddings
Select and host embedding models that suit your languages and content.
Open models →Vector and hybrid search
Combine vector, keyword and metadata search with suitable reranking.
Qdrant →Permission-aware retrieval
Apply source permissions at query time so that private content stays private.
Private AI →Evaluation
Track retrieval accuracy, citations and answer quality using test sets.
Which RAG architecture fits?
Basic RAG
Best forSimple, well-structured document collections
Watch forWeak on multi-step or cross-system questions
Hybrid RAG
Best forExact terms plus meaning, with reranking
Watch forMore components to tune and monitor
Agentic RAG
Best forQuestions that need planning across sources
Watch forHigher latency and more evaluation needed
How we build RAG infrastructure
We set up evaluation early, so every change can be measured.
Sources
Audit content, owners and permissions.
Pipeline
Build parsing, chunking and embedding.
Retrieve
Configure search and reranking.
Evaluate
Measure on real test questions.
Maintain
Refresh data and watch for drift.
RAG infrastructure design guide
Fix the content first
Reliable RAG infrastructure depends on clean sources. Remove duplicates and outdated versions, record who owns each source, and preserve document structure during parsing. Many answers that look like model errors actually begin with poor or stale content.
Choose chunks deliberately
Very small chunks lose context, while very large ones dilute relevance. Respect headings and tables, keep document and section details as metadata, and test options on real questions rather than relying on one default size.
Combine search methods
Vector search finds meaning but can miss exact product codes and names. Combining it with keyword search and a reranker often improves results. Add each component only when your tests show it helps, because each one also adds delay and cost.
Measure continuously
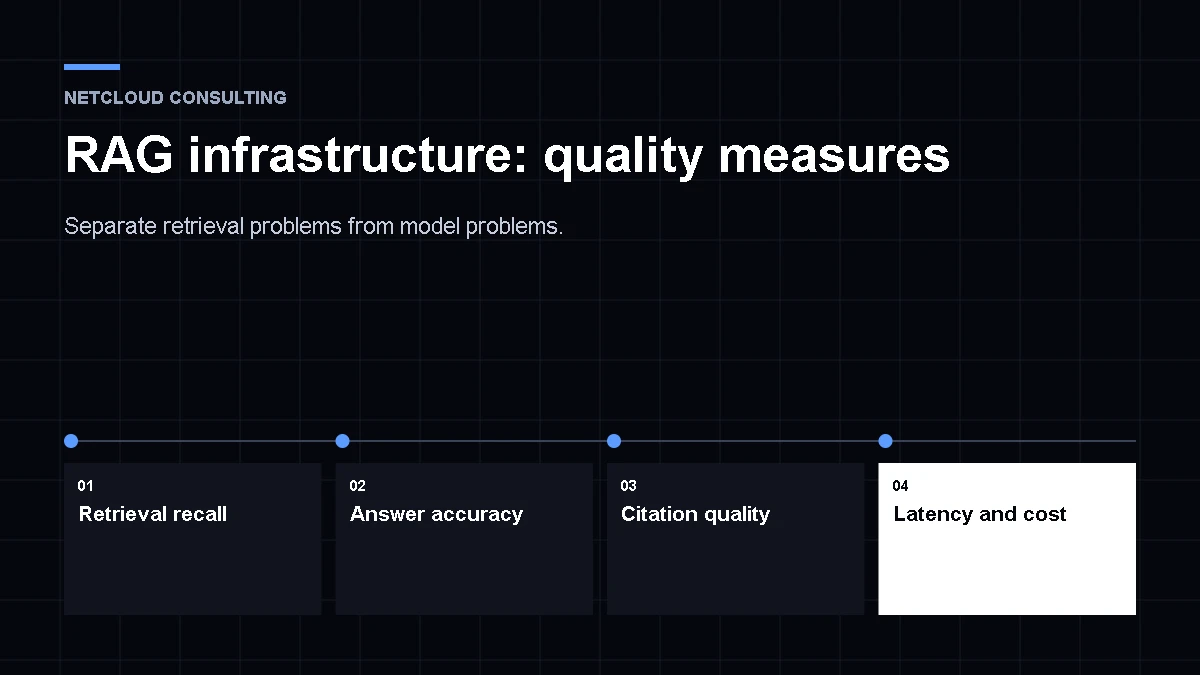
Build a test set with expected sources for each question. Track retrieval and answers separately after every change to content, embeddings or models. This shows whether a fall in quality comes from search or generation, and shortens debugging.
Official resources: Qdrant documentation, LangChain RAG tutorial and pgvector.
RAG infrastructure questions
What is the difference between RAG infrastructure and a RAG system?
RAG infrastructure is the underlying pipeline and platform. A RAG system is the finished application, such as a support or knowledge assistant, built on that foundation.
Why do RAG answers go wrong?
Common causes are poor parsing, unsuitable chunks, missing metadata and weak search. Test sets show whether the problem lies in retrieval or the model.
Can RAG run entirely on private infrastructure?
Yes. Embeddings, the vector database and the language model can all be hosted privately, as in our ARIA case study.
How often is the data refreshed?
It depends on how quickly your sources change. We can set up scheduled or event-based updates, including removal of outdated content.
Related AI infrastructure and services
Strengthen your RAG foundation
Share sample documents and questions, and we will show where your retrieval can improve.
Talk to our AI infrastructure team